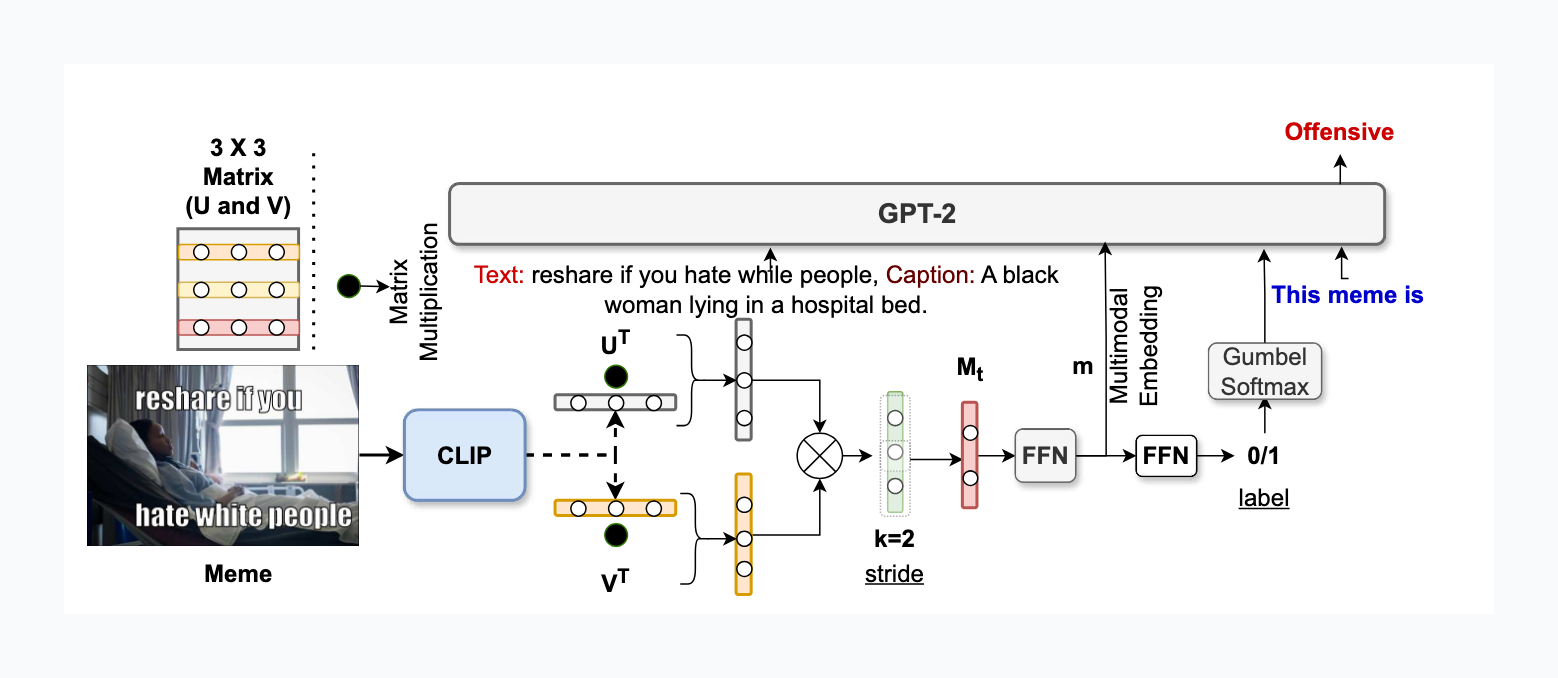
SEMANTIFY: Unveiling Memes with Robust Interpretability beyond Input Attribution
My role: Second author. Developed the Alignment-Optimization Correlation Criteria theorem for interpreting model decisions.
Method: A multi-step keyword retrieval method for explaining multimodal meme offensiveness classifiers.
Finding: Up to 2.5 points improvement on leakage-adjusted simulatability over evaluated baselines.
Scope: Automated and human explanation evaluation; results are specific to the studied tasks.
Abstract
SEMANTIFY studies explanations for multimodal meme offensiveness classifiers. Rather than restricting explanations to words present in an input, it retrieves semantically relevant keywords from a larger vocabulary through a multi-step filtering process.
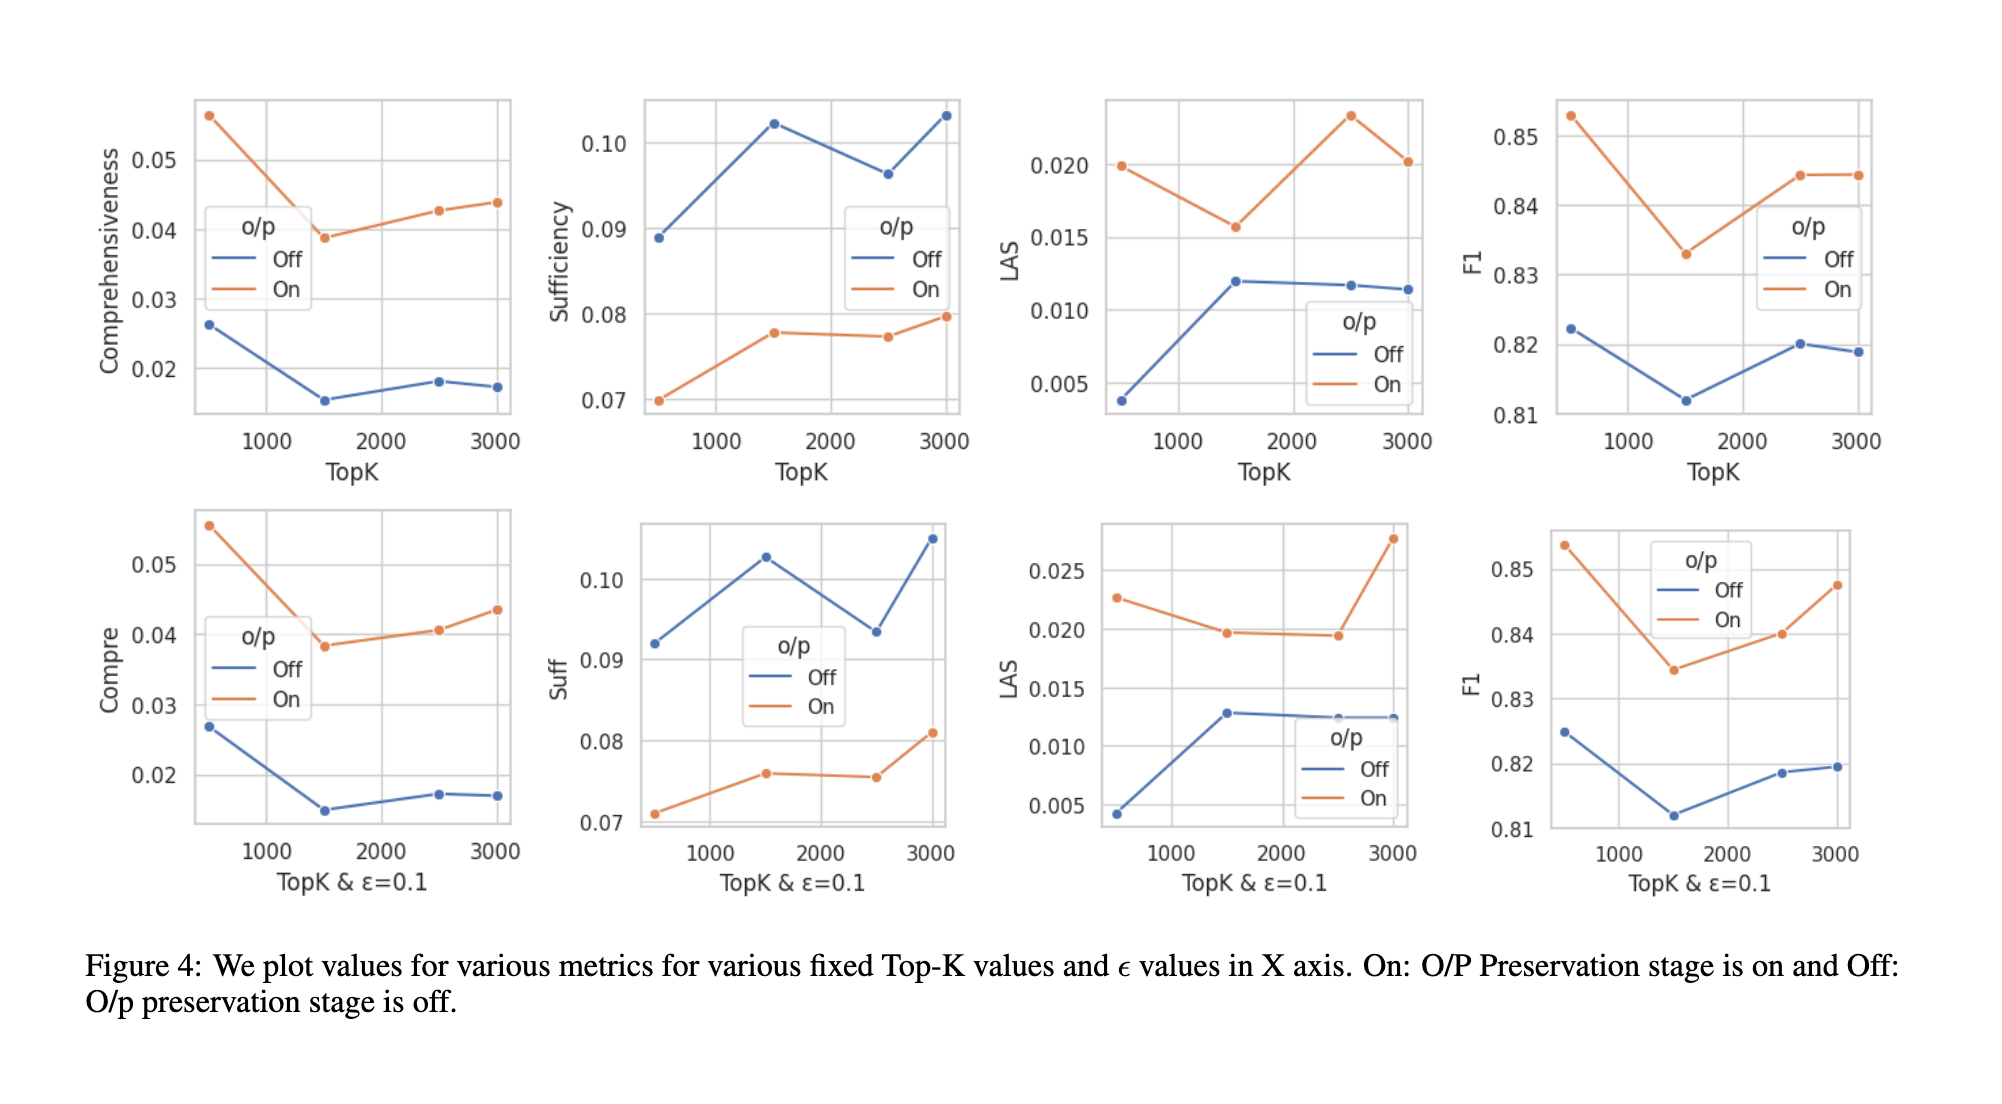
The paper evaluates explanation quality using automated interpretability metrics and human judgments of keyword relatedness and exhaustiveness. It reports gains of up to 2.5 points over evaluated baselines on leakage-adjusted simulatability, and uses qualitative examples to examine model errors. These are explanation-quality results, not a claim of improved clinical performance or general adversarial robustness.
Keywords
Visual Overview